Expanding our enterprise inference capacity with IBM Cloud and NVIDIA
Quick Answer
Together AI partners with IBM and NVIDIA to launch the first large-scale NVIDIA B300 GPU inference cluster on IBM Cloud, enhancing enterprise-grade AI capabilities.
Quick Take
This collaboration aims to meet surging demand for open models, ensuring data sovereignty and high performance at reduced costs for enterprises.
Key Points
- First dedicated NVIDIA B300 GPU cluster for inference on IBM Cloud.
- Collaboration ensures high-throughput performance with NVIDIA Spectrum-X Ethernet.
- Hundreds of trillions of tokens served monthly to over a million developers.
- Open models provide better performance at lower costs for enterprises.
- Together AI aims for scalable, reliable open-source AI solutions.
DeepSignal Analysis
What happened
Together AI has partnered with IBM and NVIDIA to establish a large-scale NVIDIA B300 GPU inference cluster on IBM Cloud. This cluster is designed specifically for enterprise-grade AI inference and is the first of its kind on the IBM Cloud platform.
Key evidence
- Together AI operates the inference layer, while IBM provides the cloud infrastructure and NVIDIA supplies the B300 GPUs and Spectrum-X Ethernet networking.
- The collaboration aims to address the increasing demand for open AI models, allowing enterprises to maintain data sovereignty while achieving high performance at lower costs.
- Together AI claims to serve hundreds of trillions of tokens monthly to over a million developers, indicating a significant growth in demand for their services.
Why it matters
This collaboration highlights a shift towards open AI models, which allow enterprises to retain control over their data while benefiting from high-performance computing. The partnership combines NVIDIA's hardware capabilities with IBM's cloud infrastructure, potentially enhancing the reliability and scalability of AI applications in enterprise settings.
What to watch
📖 Reader Mode
~2 min readWe’re excited to share that Together AI is working with IBM and NVIDIA to scale enterprise-grade AI inference, starting with a large cluster of NVIDIA B300 GPUs on IBM Cloud backed by NVIDIA Spectrum-X Ethernet networking. It's the first dedicated, large-scale inference cluster of its kind on IBM Cloud, and we're the first customer running on it.
What's actually happening
- The infrastructure: A dedicated NVIDIA B300 GPU cluster, purpose-built for inference, running on IBM Cloud.
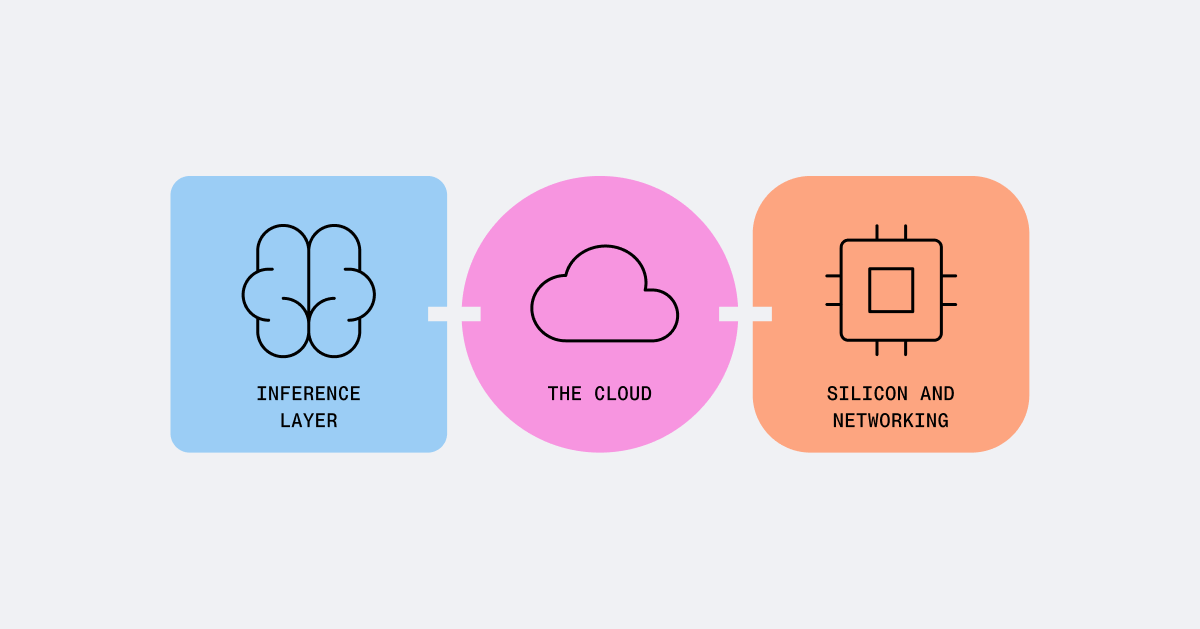
- The model: We operate the inference layer, IBM provides the cloud, NVIDIA delivers the silicon and networking.
- The trajectory: We're planning for the future as token demand goes parabolic
Why it matters
We started Together AI because we believe the future of AI shouldn't be owned by a handful of closed labs. That bet is paying off faster than even we expected: Hundreds of trillions of tokens served per month to over a million developers, and demand keeps climbing.
Enterprises and AI-native companies choose open models for two simple reasons: their sovereign data stays theirs and they get frontier-level performance at a fraction of closed-model cost. The bigger the usage, the better that math looks.
With this collaboration:
- NVIDIA brings the silicon — B300 GPUs and Spectrum-X Ethernet networking engineered for high-throughput inference.
- IBM brings decades of running mission-critical infrastructure for the world's largest enterprises.
- Together AI brings the inference platform — the fastest, most efficient way to run open models in production, hardened by some of the most demanding AI workloads on the planet.
Put those together and the result is simple: enterprise-grade inference at massive scale – more production grade tokens, with the reliability, security and guardrails enterprises have come to expect.
Open-source AI has to run everywhere, at scale, as fast and reliably as anything closed. We have spent the last few years making sure it can and this collaboration is a big step toward exactly that.
— Originally published at together.ai
Want this in your inbox every morning?
Daily brief at your local 8am — bilingual EN/中文, free.
More from Together AI
See more →
Open, convenient and predictable: Introducing Provisioned Throughput
Together AI introduces Provisioned Throughput, offering guaranteed inference capacity for MiniMax M3 and GLM-5.2 at $0.05 per PTU per minute, achieving costs up to 90% lower than Claude Opus 4.8. This new model provides predictable pricing and a 99% uptime SLA, catering to companies transitioning to open weight models for production workloads.