Cloudflare Uses an AI Harness to Probe and Harden Its WAF
Quick Answer
Cloudflare utilized AI models within a controlled harness to enhance its Web Application Firewall (WAF), generating 1,107 mutation attempts and identifying 49 significant findings, leading to three updates in its Managed Ruleset.
Quick Take
This innovative approach involved a black-box testing methodology, ensuring models adapted based on previous responses without direct access to WAF rules.
Key Points
- 1,107 mutation attempts were made, resulting in 49 relevant findings after human review.
- The AI models proposed changes to attack payloads based on previous WAF responses.
- Human reviewers validated whether requests were malicious and could be safely reproduced.
- Three changes were made to Cloudflare's Managed Ruleset, enhancing SSRF detection.
- The harness approach is similar to other security engineering systems like Google Mandiant's.
📖 Reader Mode
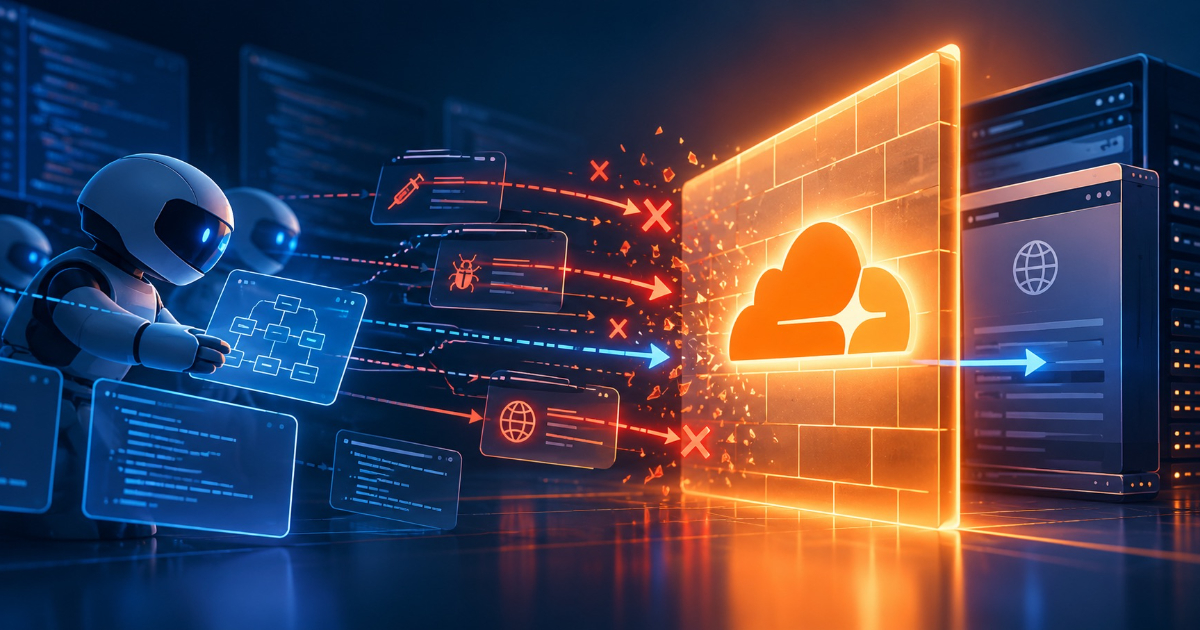
~3 min readCloudflare placed frontier AI models inside a controlled testing harness to probe its Web Application Firewall (WAF), using blocked attacks as starting points for models to generate and refine new variations.
Across 45 scenarios, the system generated 1,107 attempts and left 49 findings after human triage. The exercise ultimately contributed to three changes in Cloudflare’s Managed Ruleset.
The experiment began with attack payloads that the WAF had already blocked. Rather than repeatedly replaying fixed test cases, model calls proposed changes to their encoding, placement, or delivery based on responses from earlier attempts. The models had no access to Cloudflare’s WAF rules, source code, or internal security signals, making the test effectively black-box from their perspective.
A Python harness handled the parts Cloudflare did not want to delegate to the models. It constructed and replayed HTTP requests, maintained scenario state, enforced limits, and collected responses. One model call proposed the next mutation while another reviewed the resulting response, allowing subsequent attempts to adapt without giving the models direct control over request execution.
One SSRF test illustrates how that feedback loop worked. The tester repeatedly changed the representation and placement of a cloud metadata address, trying decimal, octal, and other forms. Eventually, a request using a decimal representation was blocked. On the next attempt, the model retained the same request shape but switched to a trailing-dot representation of the address; this time the client encountered a redirect rather than a WAF block. Cloudflare preserved the result for investigation rather than treating it as evidence that the attack had succeeded.

Source: Cloudflare
That distinction proved important at scale. Of the 1,107 recorded mutation attempts, 607 produced the post-triage result set: 558 requests blocked by the WAF and 49 findings considered relevant for further remediation work. Forty-eight of the 49 findings involved command injection or server-side request forgery (SSRF).
Human review remained the final validation step. Reviewers checked whether requests had actually reached the target, remained malicious, were clearly unblocked, fell within the WAF’s responsibility, and could be safely reproduced. Surviving cases were then replayed and evaluated as candidates for changes to rules, normalization, or other mitigations.
The work contributed to three changes in Cloudflare’s Managed Ruleset: two new detections, SSRF - Obfuscated Host and SSRF - Restricted Protocol, alongside an improvement to the existing SSRF - Cloud rule.
The same harness pattern appears elsewhere in security engineering. While Cloudflare’s Vulnerability Discovery Harness separates vulnerability discovery from independent validation, Google Mandiant’s Agentic Vulnerability Discovery Harness chains specialised agents through source-code analysis, hypothesis generation, and verification before findings reach human reviewers.

"Agentic Vulnerability Discovery Harness Chain" - Source Google
Other systems use different terminology but follow a similar discovery-and-validation pattern. OpenAI’s Codex Security builds a threat model for a repository, searches for vulnerabilities, and attempts to reproduce candidates in an isolated environment before proposing fixes for human review. Google’s PageBreak similarly focuses on validating whether AI-generated vulnerability hypotheses are actually exploitable, partly to prevent security teams being overwhelmed by plausible but unverified findings.
Across these systems, the common thread is the harness around the model: constraining execution, preserving state, validating findings, and turning probabilistic exploration into evidence that existing security workflows can use.
About the Author
Matt Foster
Show moreShow less
— Originally published at infoq.com
Want this in your inbox every morning?
Daily brief at your local 8am — bilingual EN/中文, free.
More from InfoQ AI, ML & Data Engineering
See more →Google Cloud Workbench Notebooks Extension Connects VS Code to Google Cloud's Jupyter Notebooks
The Google Cloud Workbench Notebooks extension for VS Code allows developers to seamlessly connect their local IDE to managed Jupyter notebook environments on Google Cloud, enhancing ML workflow efficiency. This integration eliminates context switching, enabling smooth transitions from local experimentation to high-performance cloud computing.