Articles tagged AI Coding.
Latest AI coding news covering coding agents, IDE tools, software engineering benchmarks, developer workflows and model updates.
DeepSignal tracks AI Coding updates across AI research, models, tools and infrastructure, highlighting high-signal stories with summaries and source-linked evidence.
Current topics: AI Coding, Research, LLM, Inference, Agent · Companies: AWS, Copilot, GitHub, Amazon
R^3 introduces a novel framework for rectifying textual violations in video ads, integrating a group-relative experience extractor and a curriculum reinforcement learning strategy. Extensive experiments show R^3 significantly outperforms existing methods, achieving a balance between compliance and semantic intent preservation in industrial applications.
The introduction of R^3, a framework for rectifying textual violations in video ads, is significant for builders and PMs as it enhances compliance without sacrificing semantic intent, potentially reducing legal risks and improving ad effectiveness. Investors should note its superior performance over existing methods, indicating a strong market demand for advanced compliance solutions in advertising technology.
This study introduces a framework for predicting item parameters from text embeddings, achieving a predictive R squared of 0.53 for item difficulty in mathematics, while highlighting the limitations in predicting discrimination and pseudo guessing parameters. The findings emphasize the importance of repeated cross-validation to avoid inflated accuracy in calibration applications.
The introduction of a framework for predicting item parameters from text embeddings, achieving a predictive R squared of 0.53, is significant for builders and PMs in educational technology. It indicates a new method for improving assessment tools, although the limitations in predicting certain parameters suggest a need for careful validation in practical applications.
This study introduces a deep learning framework for quantifying disease severity in crops, achieving 98.20% pixel accuracy with U-Net and MobileNetV2. The system categorizes stress into four levels and correlates strongly with expert assessments, enhancing automated crop monitoring.
The introduction of a deep learning framework for disease severity quantification in crops, achieving 98.20% pixel accuracy, signals a significant advancement in automated agricultural monitoring. Builders and PMs can leverage this technology to enhance precision agriculture solutions, while investors may find opportunities in agri-tech startups focused on AI-driven crop health management.
This study presents a novel approach for generating E-commerce advertising headlines using a Reinforcement Learning Policy gradient method applied to Transformer-based Masked Language Models. The proposed method significantly outperforms existing models, including LSTM + RL, in both overlap metrics and quality audits, producing headlines that surpass human-generated ones in grammar and creativity.
The development of a Reinforcement Learning Policy gradient method for generating E-commerce advertising headlines using Transformer-based Masked Language Models represents a significant advancement in AI-driven marketing tools. Builders and PMs can leverage this technology to enhance ad performance, while investors should note its potential to disrupt traditional copywriting practices and improve ROI in digital advertising.
MILES introduces a dynamic memory framework for large language models that enhances reasoning by learning selection policies for modular memory units. It outperforms existing methods in accuracy and efficiency, demonstrating robust performance across various tasks with limited supervision.
The introduction of MILES, a modular memory framework for large language models, enhances reasoning capabilities and efficiency in AI applications. Builders and PMs should consider integrating this technology to improve their models' performance while reducing the need for extensive supervision, which can lead to cost savings and faster development cycles.
CoFINN is a physics-informed deep learning framework that enhances aerodynamic force prediction in compressible flow fields, achieving up to 34% reduction in drag error at extreme angles of attack. By integrating finite-volume conservation physics directly into training, it significantly improves physical consistency while maintaining CNN computational efficiency. The framework is applicable to various conservation-law-governed systems.
The development of CoFINN, a physics-informed deep learning framework, enhances aerodynamic force predictions by integrating conservation laws into training, reducing drag error by up to 34%. This advancement is significant for builders and PMs in aerospace and automotive industries, as it offers a more accurate and efficient method for optimizing designs under extreme conditions, potentially leading to better performance and lower costs.
PALS (Percentile-Aware Layerwise Sparsity) improves transformer pruning by adjusting layer-specific sparsity based on activation magnitudes, achieving 10.96 perplexity on LLaMA-2-7B at 50% sparsity, outperforming uniform methods like Wanda (12.92 perplexity). The approach shows variable benefits across architectures and incurs negligible costs without requiring fine-tuning.
The development of PALS (Percentile-Aware Layerwise Sparsity) for LLM pruning is significant as it enables more efficient model compression, achieving lower perplexity at higher sparsity levels without the need for fine-tuning. This could lead to cost savings in deployment and improved performance for builders and PMs, while also presenting investors with opportunities in optimizing AI infrastructure.
DeLS-Spec introduces a decoupled long-short context approach to speculative decoding, enhancing DFlash's efficiency without joint training. This method achieves significant speedup and improved acceptance lengths across math, code, and dialogue benchmarks on Qwen3 models, while maintaining low training costs.
The introduction of DeLS-Spec for speculative decoding significantly enhances the efficiency of DFlash models without requiring joint training, which can lead to faster deployment and lower operational costs for AI applications. This advancement is crucial for builders and PMs looking to optimize performance while managing budgets, and it signals a promising investment opportunity in more efficient AI technologies.
The paper introduces SAMPA, a Whisper-based segmenter for Brazilian Portuguese that achieves competitive prosodic boundary detection, with F1 scores of 0.731 on a held-out test split and 0.796 on the MuPe-Diversidades dataset. This model outperforms traditional methods by leveraging deep learning techniques, specifically fine-tuning Whisper large-v3 on the NURC-SP dataset.
The introduction of SAMPA, a Whisper-based segmenter for Brazilian Portuguese, demonstrates significant advancements in prosodic boundary detection, achieving F1 scores of 0.731 and 0.796. This development signals a shift towards deep learning solutions in language processing, which could enhance applications in speech recognition and natural language understanding for builders, PMs, and investors in the AI space.

The June 2026 updates for Visual Studio Code (v1.123 to v1.127) enhance GitHub Copilot with features like an integrated browser, parallel sessions, clearer cost visibility, and improved Autopilot functionality, enabling developers to manage tasks more efficiently. These enhancements streamline workflows and provide better tools for agentic development.
The June 2026 updates to GitHub Copilot in Visual Studio Code introduce features like an integrated browser and parallel sessions, which enhance developer productivity and task management. For builders and PMs, these improvements signal a shift towards more efficient development environments, while investors should note the growing integration of AI tools in software development workflows, indicating a potential increase in demand for such solutions.

GitHub Copilot CLI streamlines the deployment of custom domains for GitHub Pages, enabling setup in just 14 minutes without manual DNS edits. By integrating with Namecheap's API, developers can automate domain registration and configuration, making custom domains accessible to all, regardless of DNS expertise.
GitHub Copilot's integration with Namecheap's API for zero DNS configuration simplifies the deployment of custom domains for GitHub Pages, significantly reducing the technical barrier for developers. This development allows teams to focus on product features rather than infrastructure setup, making it a compelling signal for investors interested in tools that enhance developer productivity.

Jamf's AI Governance integrates with Amazon Bedrock to manage AI applications like Claude Code on Macs, enabling centralized configuration and deployment without manual setup. This solution enhances efficiency by reducing costs and latency in coding workflows, with prompt caching cutting costs by up to 90% and latency by 85%. IT teams can easily validate policy coverage across devices.
Jamf's integration of AI Governance with Amazon Bedrock allows for centralized management of AI applications on Macs, significantly reducing deployment costs and latency. This development is crucial for builders and PMs as it streamlines workflows and enhances efficiency, while investors should note the potential for cost savings and improved productivity in AI-driven environments.

OpenAI's GPT-5.6 models launch on Thursday after a delay due to U.S. government restrictions. The Sol Ultra model achieved a leading 91.9% on the TerminalBench 2.1 coding benchmark, outperforming competitors like Anthropic's Claude Mythos 5 and Google's Gemini 3.1 Pro Preview. OpenAI criticized the delay for hindering developer access to advanced tools.
The launch of OpenAI's GPT-5.6, particularly the Sol Ultra model achieving a 91.9% on the TerminalBench 2.1 coding benchmark, signals a significant advancement in AI capabilities. This development provides builders and PMs with access to more powerful tools for coding and automation, while investors should note the competitive edge it gives OpenAI over other AI models in the market.
The study introduces LLMForge, a multi-model framework for automatic CAD generation, achieving 98.97% mesh success with models like DeepSeek-V3.2 and Qwen3-235B-A22B. It highlights the effectiveness of compact instruction-tuned models compared to larger systems, while also addressing challenges in generating rotationally symmetric geometries.
The introduction of LLMForge for automatic CAD generation with a 98.97% mesh success rate signals a significant advancement in design automation, allowing builders and PMs to streamline workflows and reduce costs. Investors should note the potential for compact instruction-tuned models to disrupt traditional CAD processes, enhancing efficiency in engineering and manufacturing sectors.
CSTutorBench introduces a benchmark for evaluating small language models (SLMs) as tutors in block-based programming, revealing that while models excel in vocabulary and tone, they struggle with deeper pedagogical behaviors. The study indicates that model family and instruction-tuning are better predictors of tutoring quality than parameter count alone, with targeted prompt revisions improving performance for 10 out of 11 models tested.
The introduction of CSTutorBench provides a critical framework for assessing small language models as educational tools, highlighting that model family and instruction-tuning are key to effective tutoring. This insight allows builders and PMs to focus on refining these aspects in their AI products, while investors can identify promising innovations in the educational AI space based on these benchmarks.
The Scene Graph Thinking (SaGe) paradigm enhances Multimodal Large Language Models (MLLMs) by integrating structured visual reasoning through scene graphs, achieving significant improvements across eight multimodal benchmarks. The approach includes an automated data engine for creating structured scene graphs and a two-stage graph-aligned post-training method, resulting in enhanced fine-grained perception and reasoning capabilities.
The development of the Scene Graph Thinking (SaGe) paradigm enhances Multimodal Large Language Models by integrating structured visual reasoning, which can significantly improve applications in areas like computer vision and natural language processing. Builders and PMs should consider leveraging this approach to create more sophisticated AI systems that can understand and interpret complex visual information effectively.
This study compares Byte-Pair Encoding (BPE) and Unigram-LM for tokenizing SMILES in chemistry, revealing they generate nearly disjoint vocabularies with a maximum Jaccard overlap of 0.161. Unigram-LM produces 29-41% more tokens than BPE, indicating a significant difference in segmentation depth across various corpus types and vocabulary sizes.
The study highlights the differences in tokenization methods for chemical SMILES, specifically that Unigram-LM generates significantly more tokens than Byte-Pair Encoding. This has practical implications for builders and PMs in developing more effective NLP models for chemistry applications, influencing how they approach data preprocessing and model training.
ResonatorLM introduces a novel mechanism that replaces traditional attention in transformers with damped resonators for long-context language modeling, achieving a 6.47x speedup in decoding at 32K tokens and improving accuracy to 61.31% on WikiText compared to 55.32%. This advancement is particularly beneficial for tasks requiring efficient processing of extensive token sequences.
The introduction of ResonatorLM, which replaces traditional attention mechanisms with damped resonators, offers a significant 6.47x speedup in decoding for long-context language models. This advancement is crucial for builders and PMs focusing on applications that require processing large token sequences efficiently, while investors should note its potential to enhance performance and reduce costs in AI-driven solutions.
This study evaluates the effectiveness of domain adaptation in sentiment analysis using frozen pre-trained language models like Qwen3 and FinBERT. Results show negligible gains on SST-2 movie reviews but significant performance recovery on financial news with small backbones, highlighting that adaptation efficacy depends on existing target-domain knowledge in the backbone.
The study on domain adaptation in sentiment analysis reveals that using frozen pre-trained models like Qwen3 and FinBERT may not always yield improvements, particularly in domains with limited target knowledge. This insight is crucial for builders and PMs when selecting models for specific applications, as it emphasizes the need for careful evaluation of model suitability based on domain characteristics.
The study compares full-corpus injection against two structured retrieval methods, NAVEMBED and NAVINDEX, for analyzing transactional legal documents. NAVINDEX achieved a 1.61x smaller token footprint and 25% lower costs while maintaining competitive performance, scoring tied on all 18 benchmark questions. Cached injection is only cheaper when the corpus is under ten times the retrieval payload.
The study highlights the NAVINDEX retrieval method, which offers a 1.61x smaller token footprint and 25% lower costs for analyzing legal documents compared to traditional injection methods. This is significant for builders and PMs looking to optimize AI costs and performance in legal tech applications, while investors should note the potential for reduced operational expenses and improved efficiency in AI-driven document analysis.
The MuCoDi framework distills embeddings from multiple pathology foundation models into compact encoders, achieving up to 71.0% AUROC with reduced model sizes. MobileOne students on Raspberry Pi 5 demonstrate a 605-fold speedup over Virchow2 while maintaining competitive performance, enabling practical edge deployment in pathology.
The MuCoDi framework enables the creation of compact pathology models that maintain high performance while significantly reducing resource requirements. This advancement allows builders and PMs to deploy AI in edge environments, such as mobile devices, leading to faster diagnostics in healthcare and opening investment opportunities in efficient AI applications.
The Ladderpath approach introduces a novel method for analyzing nested and hierarchical relationships in linguistic sequences, leveraging Algorithmic Information Theory. This method provides three distance measures that outperform gzip-based NCD and BERT in out-of-distribution and low-resource text classification tasks, highlighting its potential for lightweight and interpretable text modeling.
The Ladderpath approach introduces a new method for analyzing linguistic sequences that outperforms traditional compression techniques and BERT in specific tasks. This advancement could enable builders and PMs to develop more efficient and interpretable text models, while investors may find opportunities in startups leveraging this innovative approach for enhanced NLP applications.
NAVER LABS re-implements its IWSLT 2025 instruction-following pipeline for the IWSLT 2026 Shared Task using SeamlessM4T-v2-large and Qwen3-4B-Instruct. The model achieves COMET 0.781 on EN-ZH speech translation and BERTScore-F1 0.346 on the MCIF benchmark, bolstered by 100k synthetic instruction-following examples across ten task types.
NAVER LABS' re-implementation of its instruction-following pipeline using SeamlessM4T-v2-large and Qwen3-4B-Instruct demonstrates significant advancements in speech translation and instruction adherence, achieving high performance metrics. This development signals to builders and PMs the potential for improved user interaction in AI applications, while investors may see opportunities in enhanced language processing technologies.
ArtisanCAD introduces a skill-guided industrial CAD agent that utilizes expert-grounded knowledge distillation to enhance CAD generation. By employing a CAD intermediate representation (CAD-IR), it reduces mean Chamfer Distance from 14.83 to 9.88 on the Text2CAD benchmark, effectively bridging ambiguous prompts and executable CAD operations. This innovation allows for the generation of editable CATIA-native B-Rep models from expert recordings.
The introduction of ArtisanCAD, an industrial-level CAD agent utilizing expert-grounded knowledge distillation, significantly improves the accuracy of CAD generation, reducing mean Chamfer Distance on the Text2CAD benchmark. This advancement enables builders and PMs to create more precise and editable CAD models efficiently, which can lead to faster project turnaround and reduced costs for investors.
Nemotron-Labs-Diffusion is a tri-mode language model that integrates autoregressive, diffusion, and self-speculation decoding, achieving 76.5% more tokens per forward pass than self-speculation. The model, scaling up to 14B parameters, outperforms existing AR and diffusion models in accuracy and speed, exemplified by its 6x token decoding advantage over Qwen3-8B on SPEED-Bench with SGLang.
The introduction of the Nemotron-Labs-Diffusion model, which combines autoregressive, diffusion, and self-speculation decoding, is significant for builders and PMs as it enhances token processing efficiency by 76.5%, enabling faster and more accurate language applications. Investors should note its competitive edge over existing models, indicating potential for improved performance in AI-driven products.
PCBWorld is an open-source PCB routing environment utilizing the KiCad EDA engine, enabling agents to interactively route boards while adhering to design rules. Experiments show that agents in PCBWorld outperform traditional RL policies and baselines, demonstrating significant potential for enhancing PCB design automation.
The development of PCBWorld as an open-source PCB routing environment using the KiCad EDA engine signifies a major advancement in PCB design automation, allowing builders and PMs to leverage AI for more efficient design processes. This could lead to reduced time-to-market and lower costs, making it an attractive opportunity for investors in the hardware and automation sectors.
Prompt-to-Paper introduces a AI framework that enhances bioinformatics manuscript generation by grounding claims in verifiable literature, executing real experiments, and providing standardized quality assessments, achieving an average quality increase of 17.96 points on a 0-100 scale at a cost of approximately $0.31 per paper.
The introduction of the Prompt-to-Paper multi-agent AI framework significantly enhances the efficiency and quality of bioinformatics manuscript generation, allowing researchers to produce high-quality papers at a low cost. This development signals a shift towards automated, reliable scientific writing, which could attract investment in AI-driven research tools and streamline workflows for builders and PMs in the biotech sector.
This paper introduces a black-box evaluation framework for assessing LLMs in generating Design Structure Matrices (DSMs) from technical documentation. The framework benchmarks generated DSMs against validated matrices, revealing LLMs' potential and limitations in producing structurally plausible DSMs while highlighting issues with ambiguity and prompt formulation. Results indicate high reproducibility under structured inputs, establishing a transparent benchmark for Auto-DSM pipelines.
The introduction of a black-box evaluation framework for LLMs in generating Design Structure Matrices (DSMs) provides builders and PMs with a reliable method to assess the effectiveness of AI tools in structuring technical information. Investors should note that this transparency can enhance the trustworthiness and applicability of LLMs in engineering contexts, potentially leading to better investment decisions in AI-driven design solutions.
MemDefrag introduces a training-free, model-agnostic framework for latent memory defragmentation in large language models, significantly improving knowledge retention (43.0% vs. 17.4%/17.6% after 50 updates) and long-context benchmarks. By utilizing a middle-layer tracing signal, it effectively ranks, reorders, and filters memories, addressing performance degradation during updates.
The introduction of MemDefrag, a training-free framework for latent memory defragmentation, enhances knowledge retention in large language models by up to 43%. This development is crucial for builders and PMs as it enables more efficient updates and better long-context performance, potentially reducing costs and improving user experience in AI applications.
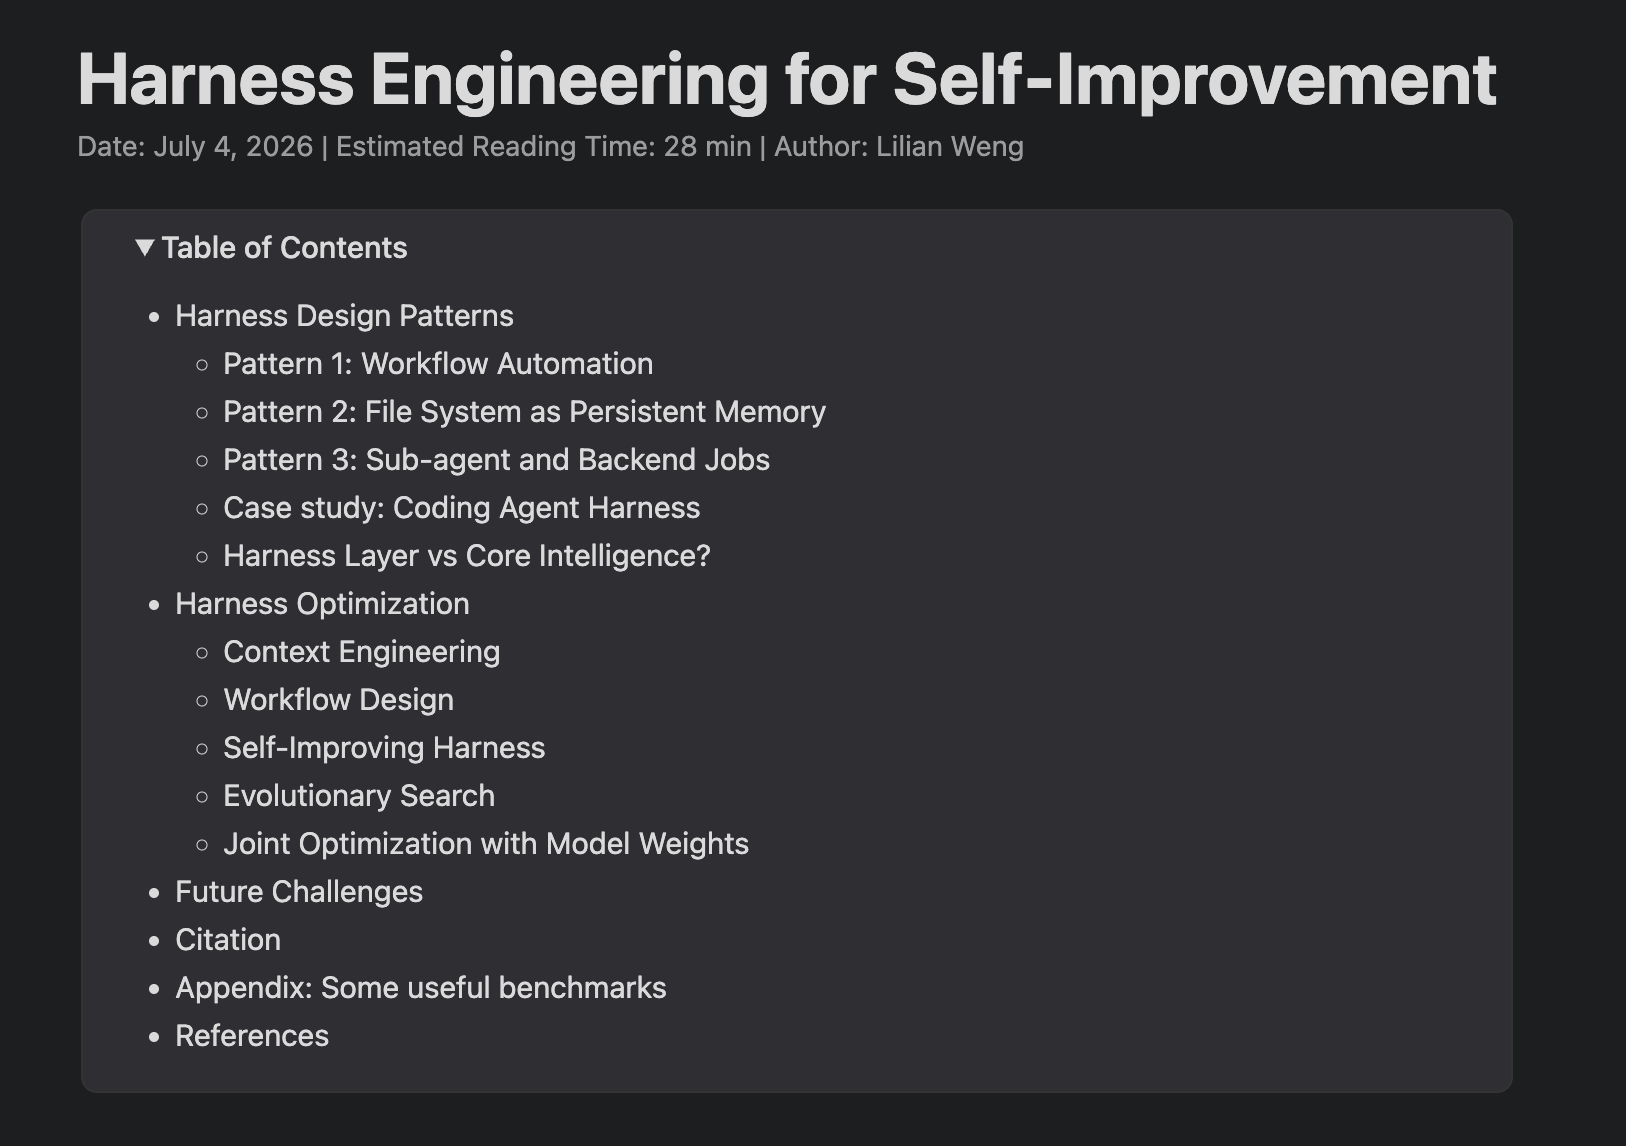
![[AINews] Lilian Weng summarizes 35 papers on Harness Engineering for RSI](https://substackcdn.com/image/fetch/$s_!L_Ci!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fsubstack-post-media.s3.amazonaws.com%2Fpublic%2Fimages%2F603a46c6-cedc-4b38-a660-2fa1d4b3f4ba_1626x1146.png)
Lilian Weng's latest post discusses harness engineering's role in recursive self-improvement (RSI) for AI, emphasizing its potential to enable auto-research and smarter models. She highlights key design trends and literature, including the ACE paper and Meta-Harnesses, while noting that goal specification remains crucial even as harness improvements are integrated into core models.
Lilian Weng's summary of 35 papers on harness engineering for recursive self-improvement (RSI) highlights the importance of integrating advanced harness designs, like Meta-Harnesses, into AI models. This development signals a shift towards more autonomous AI systems capable of self-research, which could enhance product capabilities and drive investment opportunities in AI innovation.