Articles tagged AI Video.
DeepSignal tracks AI Video updates across AI research, models, tools and infrastructure, highlighting high-signal stories with summaries and source-linked evidence.
Current topics: AI Video, Research, Open Source, Inference, Robotics · Companies: Google, DeepMind, Google DeepMind, Gemini
RACER introduces a training-free framework for long video frame selection, addressing the Query Comprehension and Interpretation-Selection Gaps. By utilizing a lightweight Vid- for query reformulation and an embedding model for evidence localization, RACER enhances frame selection effectiveness, demonstrating improved performance across benchmarks even with limited-capability components.
The introduction of RACER, a training-free framework for long video frame selection, significantly improves query comprehension and evidence localization, which can enhance user experience in video applications. Builders and PMs should consider integrating this technology to streamline video content retrieval, while investors may see potential for scalable solutions in the growing video analysis market.
SPW-Nav is a novel streaming panoramic world model that generates 2K 360-degree video in real-time, outperforming previous models in camera-following accuracy and video quality. It interprets movement instructions to create interactive panoramic videos, enabling applications in virtual reality and embodied agent training.
The development of SPW-Nav, a real-time streaming panoramic world model that generates high-quality 360-degree video, is significant for builders and PMs as it enhances immersive experiences in virtual reality and improves training for embodied agents. Investors should note its potential to disrupt existing VR technologies and create new market opportunities in interactive media and AI-driven navigation.
The paper introduces MOTIVE, a Multi-View Self-Verification framework that enhances the reliability of Vision-Language Models (VLMs) by evaluating answers from multiple perspectives. Extensive experiments show that MOTIVE outperforms existing self-verification methods, improving decision-making in multimodal reasoning without external judges.
The introduction of the MOTIVE framework enhances the reliability of Vision-Language Models by enabling multi-perspective self-verification, which is crucial for applications requiring accurate multimodal reasoning. Builders and PMs can leverage this advancement to improve product performance, while investors should note its potential to drive innovation in AI-driven solutions.
VCR-Bench is a new open-source benchmark for video classification that standardizes evaluation across 30 models and 14 adversarial attacks. It facilitates reproducibility in robustness studies by providing a unified framework for video loading, metrics, and logging. The benchmark has been tested on the Kinetics-400 dataset, reporting key performance metrics such as accuracy and attack success rates.
The launch of VCR-Bench, a modular open-source benchmark for video classification, standardizes evaluation across various models and adversarial attacks, which is crucial for builders and PMs to ensure robustness in their AI systems. For investors, this development signals a growing focus on reliable AI performance, potentially leading to more secure and trustworthy applications in the video classification domain.

Google's SynthID Detector is now public, identifying invisible watermarks in 180 billion images and videos from its AI models like Gemini and Veo. The tool supports various formats and integrates with Google Search and Chrome, handling one million verification requests daily.
Google's public release of the SynthID Detector, which identifies invisible watermarks in 180 billion images and videos, signifies a critical advancement in content authenticity verification. This development is essential for builders and PMs focused on trust and security in AI-generated content, while investors should note its potential impact on the market for digital rights management and content verification solutions.

Google DeepMind has launched EmbeddingGemma 2, a multimodal embedding model with 740 million parameters, optimizing on-device performance for text, images, audio, and video. It achieves top-tier benchmarks, including a 9.92-point increase in code performance, while ensuring data privacy and reducing latency for developers building cross-modal applications.
The launch of Google DeepMind's EmbeddingGemma 2, a multimodal embedding model optimized for on-device performance, is significant for builders and PMs as it enables the development of efficient cross-modal applications with enhanced data privacy and reduced latency. Investors should note its top-tier benchmarks, indicating strong potential for market adoption and competitive advantage in AI-driven solutions.

The ECCV 2026 conference highlighted the shift towards spatial intelligence in AI, emphasizing 3D understanding, world models, and dynamic scene prediction. With over 10,000 submissions, key topics included scalable 3D reconstruction and interactive navigation benchmarks like WalkerBench, which improved performance by 104.97%. Notable awards went to Li Fei-Fei's team for their contributions to spatial intelligence.
The ECCV 2026 conference underscored the importance of spatial intelligence in AI, particularly through advancements in 3D reconstruction and interactive navigation benchmarks like WalkerBench, which significantly enhance vision-language model (VLM) performance. Builders and PMs should consider integrating these technologies to improve user experiences in applications requiring real-world interaction, while investors may find opportunities in startups focusing on spatial AI solutions.
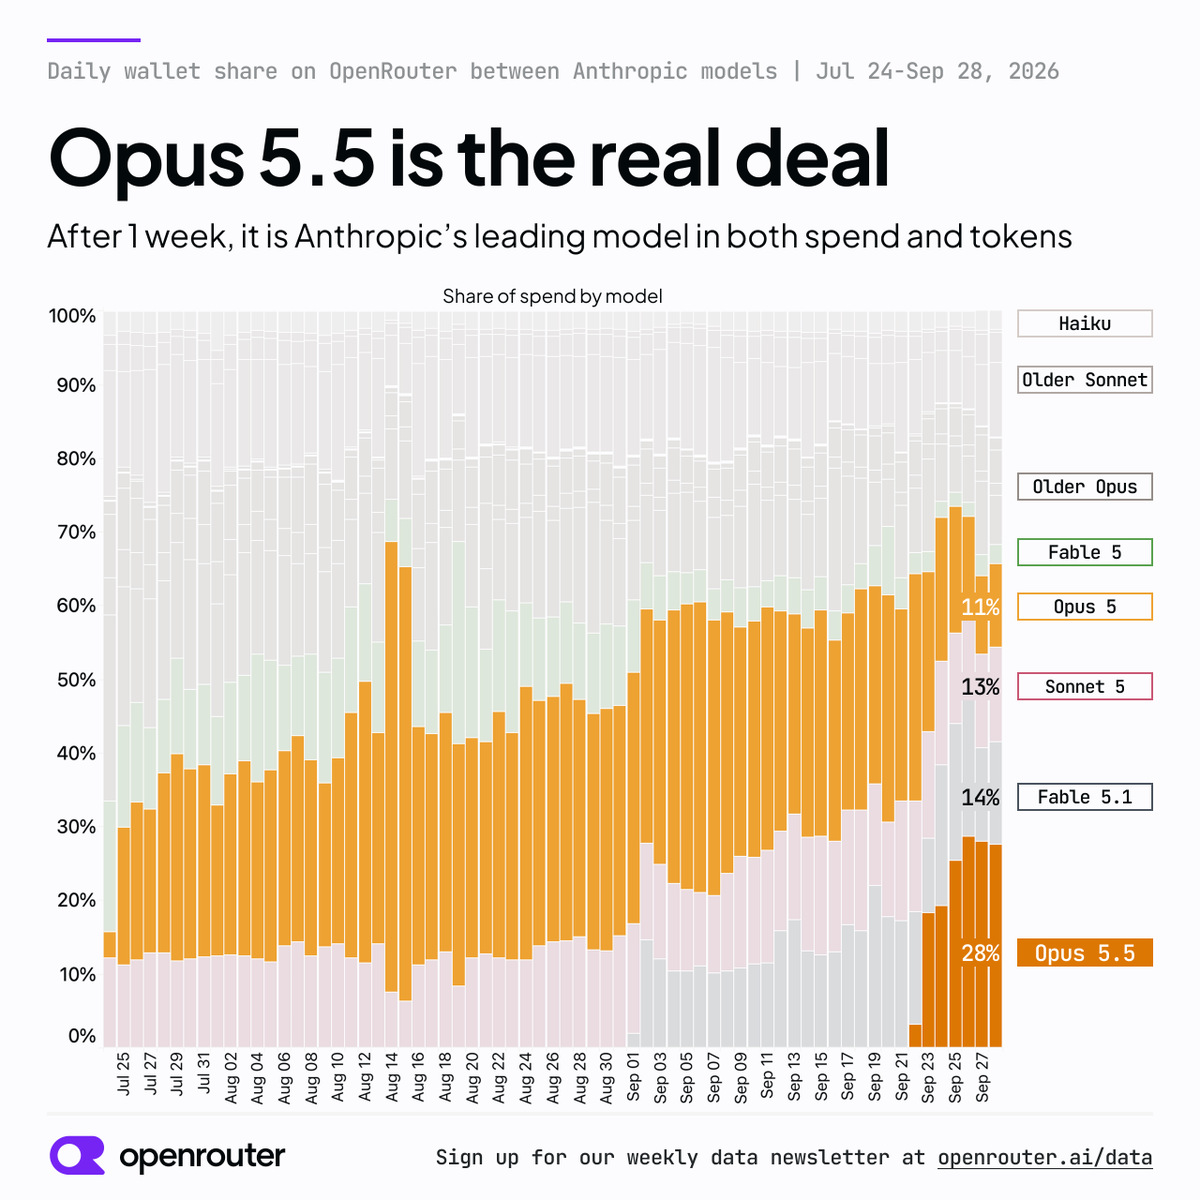
![[AINews] Opus 5.5 is good at explainer videos](https://substackcdn.com/image/fetch/$s_!aAiz!,f_auto,q_auto:good,fl_progressive:steep/https%3A%2F%2Fpbs.substack.com%2Fmedia%2FHTVRIbeagAAvWK1.png)
Opus 5.5 has quickly become the leading model for explainer videos, outperforming previous versions with rapid adoption and impressive motion design capabilities. It ranks first in share of spend and tokens among Anthropic models on OpenRouter, achieving a 62% reasoning effort at high settings and significantly lower costs than competitors.
The release of Opus 5.5, which excels in creating explainer videos with advanced motion design and cost efficiency, signals a shift in content creation tools that builders and PMs can leverage for higher engagement and lower production costs. For investors, its rapid adoption and leading market position indicate a strong potential for ROI in the AI content generation space.

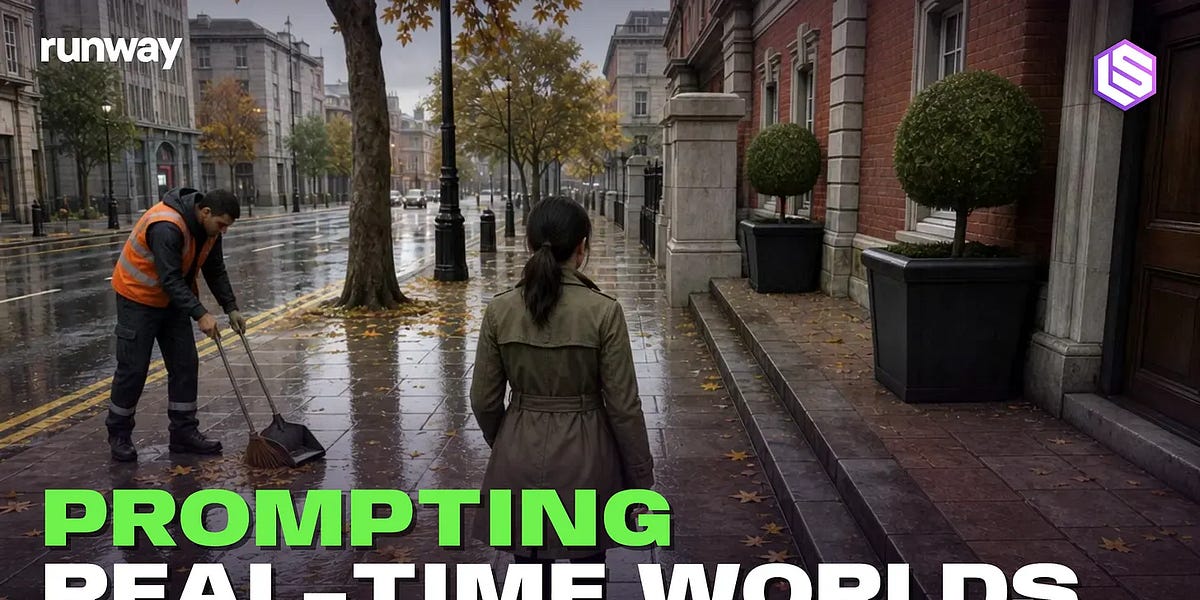
Runway's GWM Worlds 2 introduces WorldPrompt, enabling real-time interactive video and audio generation with autoregressive diffusion. Valued at $5.3 billion, Runway aims to create self-generated experiences, overcoming challenges like error accumulation and long-term memory limitations.
Runway's introduction of WorldPrompt for real-time interactive video and audio generation signifies a major advancement in content creation tools, allowing builders and PMs to develop more immersive experiences with reduced error accumulation. For investors, this innovation highlights Runway's potential for scalable applications in entertainment and education, positioning it as a strong player in the AI landscape.

Google Research introduces an AI video co-director framework that enhances long-form video generation by ensuring visual continuity and narrative coherence. Utilizing models like Gemini and Veo, it automates creative processes, significantly reducing semantic drift and pipeline errors, resulting in consistent multi-shot narratives.
Google Research's introduction of an AI video co-director framework automates long-form video generation, enhancing visual continuity and narrative coherence. This development signals a shift towards more efficient content creation processes, reducing costs and time for builders and PMs while presenting investors with opportunities in the growing AI-driven media landscape.

Google DeepMind has launched agentic video understanding in Gemini models (3.7 Flash, 3.6 Flash, 3.5 Flash-Lite), achieving up to 88% reduction in token consumption and 66% cost savings while improving accuracy by 7%. This feature allows dynamic video analysis, enhancing capabilities such as moment retrieval and anomaly detection, and is available via the Gemini API.
Google DeepMind's launch of agentic video understanding in Gemini models significantly reduces token consumption by 88% and costs by 66%, while improving accuracy by 7%. This advancement allows builders and PMs to implement more efficient and cost-effective video analysis solutions, enhancing applications like moment retrieval and anomaly detection, which can attract investor interest in AI-driven video technologies.

MiniMax H3, an open-weight video model, successfully generated a video depicting the process of a cat breaking a vase, demonstrating its potential for causal event reconstruction. In contrast, Seedance 2.0 Fast outperformed H3 in terms of speed and realism, completing a similar task in just 3 minutes compared to H3's 54 minutes, highlighting the efficiency gap between open-source and closed-source models.
The successful demonstration of MiniMax H3 in causal event reconstruction and the superior performance of Seedance 2.0 Fast highlight the growing capabilities of AI in video generation. Builders and PMs should consider the implications for user engagement and content creation, while investors may see opportunities in the efficiency and realism offered by advanced models.

Google DeepMind's Gemini Omni 1.1 Flash enhances generative video production with features like scene extension, frame interpolation, and 4K upscaling, enabling faster prototyping and professional-quality outputs. Developers can now create seamless videos with improved narrative consistency and reduced costs, generating previews up to 60% faster at 360p resolution.
Google DeepMind's Gemini Omni 1.1 Flash introduces advanced features for generative video production, allowing developers to create high-quality videos more efficiently. This development signals a significant reduction in production costs and time, making it easier for builders and PMs to prototype and iterate on video content, while investors can see potential for growth in the content creation market.

Google Research's AMIE (Video) enhances clinical consultations by integrating real-time audio-visual cues, achieving expert-level performance in a study with 300 consultations and 30 physicians. This asynchronous architecture improves diagnostic reasoning while maintaining natural conversational flow.
Google Research's AMIE (Video) development significantly enhances clinical consultations by integrating real-time audio-visual cues, improving diagnostic accuracy and efficiency. This advancement signals a potential shift towards AI-driven healthcare solutions that can support medical professionals, making it a valuable area for builders, PMs, and investors to explore in the health tech landscape.

The paper 'Masked Visual Actions for Unified World Modeling' proposes that robots can utilize existing video generation models like Wan2.2 without needing dedicated models, achieving superior performance with just 15 hours of fine-tuning. This approach challenges conventional robotics paradigms, potentially revolutionizing the industry by simplifying the integration of robotic systems across different platforms.
The paper 'Masked Visual Actions for Unified World Modeling' suggests that robots can leverage existing video generation models like Wan2.2 for enhanced performance with minimal fine-tuning. This development simplifies the integration of robotics across platforms, reducing time and costs for builders and PMs, while presenting investors with opportunities in a rapidly evolving robotics market.

Ant Group's four papers for IJCAI 2026 focus on adapting AI to dynamic environments, showcasing models like MSRGC-Net achieving 80% optimal rates in clustering, ROAD improving reinforcement learning strategies, DSEBO optimizing high-dimensional searches, and VGA-BenchV2 enhancing video quality assessments. These advancements address real-world challenges in AI deployment across diverse applications.
Ant Group's development of models like MSRGC-Net and ROAD demonstrates significant advancements in AI adaptability and efficiency. This is crucial for builders and PMs as it enables the deployment of more effective AI solutions in dynamic environments, while investors should note the potential for these innovations to drive competitive advantages in various sectors.
CLIP-CC-Bench introduces a novel evaluation suite for long-form video descriptions, utilizing 90-second clips from 5 hours of movie content paired with expert-written references. It employs five -based models for reliable semantic matching, assessing 17 state-of-the-art video-language models and providing standardized evaluation tools for reproducibility.
The introduction of CLIP-CC-Bench as an evaluation suite for long-form video descriptions provides builders and PMs with standardized tools to assess and improve video-language models effectively. This development signals a growing emphasis on semantic accuracy in AI, which can influence investment strategies focused on media and content generation technologies.
Dynamic Latent Reasoning (DyLaR) enhances video question answering by grounding queries in visual evidence and adaptively deciding when to reason, achieving an accuracy increase from 54.0 to 58.2 on Qwen3-VL-4B while reducing response length from 1,220.7 to 18.5 tokens. This method outperforms existing baselines across nine benchmarks, demonstrating the effectiveness of grounded perception and adaptive reasoning.
The development of Dynamic Latent Reasoning (DyLaR) for video question answering significantly improves accuracy and reduces response length, indicating a shift towards more efficient AI models that combine perception and reasoning. Builders and PMs can leverage this approach to enhance user interaction in video-based applications, while investors may see potential in startups adopting such advanced AI techniques.
muSync-GS introduces a physics-synchronized framework for synthesizing driving videos under adverse weather and road conditions, achieving RMSEs of 0.0273 m/s for speed and 0.0590 degrees for pitch. This model enhances the realism of autonomous driving simulations by coupling road conditions with vehicle dynamics, addressing challenges in data collection for rare scenarios.
The development of muSync-GS, a physics-synchronized framework for synthesizing driving videos, significantly enhances the realism of autonomous driving simulations. This is crucial for builders and PMs in the automotive tech space as it improves safety testing and reduces the need for extensive real-world data collection, making it a valuable tool for investors looking to support innovative simulation technologies.
OmniVR is a groundbreaking joint audio-video generative restoration model that effectively restores degraded historical films by addressing visual and audio issues simultaneously. Leveraging a 22B-parameter backbone, it outperforms previous methods across six visual metrics and achieves superior audio quality. The introduction of OmniVRBench sets a new standard for evaluating restoration quality on 200 historical clips.
The launch of OmniVR, a joint audio-video generative restoration model, represents a significant advancement in restoring historical films, offering builders and PMs a new tool for media preservation and content enhancement. For investors, this technology could open new revenue streams in the growing market for digital restoration and archival services, leveraging its superior performance metrics.
CofactVLA introduces a novel causal intervention framework to address the vision-override issue in Vision-Language-Action models, achieving state-of-the-art results in simulations and a 52.3% success rate improvement in real-world robotic tasks under out-of-distribution scenarios.
The introduction of CofactVLA's causal intervention framework addresses the vision-override issue in Vision-Language-Action models, significantly improving their performance in real-world robotic tasks. This advancement offers builders and PMs a pathway to enhance AI robustness in diverse environments, while investors can recognize the potential for greater reliability in AI applications, leading to increased market competitiveness.
CAPE-T2V introduces a two-step framework for enhancing prompt alignment in text-to-video generation, significantly reducing the PE-Caption gap. It fine-tunes the prompt enhancer and diffusion transformers, achieving superior performance on benchmarks like StoryEval and VBench-2.0, with closer distributions in captions during inference. This approach demonstrates a more effective alignment between training and inference outputs.
The development of CAPE-T2V enhances text-to-video generation by improving prompt alignment, which can lead to more accurate and contextually relevant video outputs. For builders and PMs, this means better tools for content creation, while investors should note the potential for increased market demand in AI-driven media solutions.
The V-FIND framework uncovers and activates sparse forensic knowledge in video forgery detectors, enhancing detection performance without full model retraining. By identifying specialized neurons, it organizes them into a compact subspace, achieving strong results across benchmarks while maintaining the original model's integrity.
The V-FIND framework enhances video forgery detection by activating specific neurons without retraining the entire model, which can significantly reduce development time and costs for builders and PMs. For investors, this advancement signals a more efficient path to deploying robust AI solutions in security and content verification markets.
The Crayotter model, utilizing Group-Relative Preference Backpropagation (GRPB), enhances long-horizon video editing by improving subjective feedback handling, surpassing proprietary systems on AgenticVBench. It effectively transforms ordinal comparisons into actionable insights, leading to better editing outcomes and quality.
The Crayotter model's use of Group-Relative Preference Backpropagation (GRPB) for long-horizon video editing represents a significant advancement in subjective feedback processing, allowing for improved editing outcomes. Builders and PMs can leverage this technology to enhance user experience in video applications, while investors may see potential for competitive differentiation in the growing video editing market.

NVIDIA's shift from Vision-Language-Action (VLA) models to World Action Models (WAM) enhances robotic manipulation by integrating a video world model, allowing for better generalization and fewer data requirements. The Cosmos 3 model, with 767M images and 348M videos, supports this transition, improving task success rates from 28.1% to 36.8% in RoboLab benchmarks.
NVIDIA's introduction of World Action Models (WAM) significantly enhances robotic manipulation capabilities by leveraging a video world model, which improves generalization and reduces data needs. This shift, evidenced by increased task success rates in RoboLab benchmarks, signals a critical advancement for builders and PMs in robotics, indicating a trend towards more efficient and capable AI-driven automation solutions.
The DAR model enhances video diffusion rendering by integrating camera motion and animated mesh conditions, achieving PSNR of 25.36 on the DAR-4D benchmark. This approach outperforms existing methods by improving PSNR by up to 1.54 dB, demonstrating the effectiveness of tracking and world position in 4D rendering.
The DAR model's advancement in video diffusion rendering, achieving a PSNR improvement of 1.54 dB, signals a significant leap in 4D rendering technology. Builders and PMs can leverage this for enhanced visual fidelity in applications like gaming and virtual reality, while investors may see potential in startups focused on next-gen rendering solutions.
LeapTalk introduces a novel framework for real-time talking-head generation, achieving high-fidelity video output at 200 FPS with a single forward step. By utilizing a unique data-to-data transport formulation and a heterogeneous distillation framework, it effectively reduces identity drift and enhances temporal stability, outperforming existing methods in efficiency and stability.
LeapTalk's real-time talking-head generation at 200 FPS with high fidelity represents a significant advancement in video synthesis technology. This development allows builders and PMs to create more engaging and lifelike virtual interactions, while investors can capitalize on the growing demand for high-quality video content in applications like teleconferencing and entertainment.

MiniMax's H3 model becomes the first open AI video model to top a ranking, achieving first in Video Editing, second in Text-to-Video, and third in Image-to-Video. With 33 billion parameters, it generates clips of 4-15 seconds, but commercial use is restricted to companies earning under $20 million.
The MiniMax H3 model's achievement as the first open AI video model to top a ranking indicates a significant advancement in accessible AI tools for video content creation. Builders and PMs should note its potential for democratizing video editing and production, while investors may see opportunities in companies leveraging this technology under the specified commercial restrictions.

Andrej Karpathy utilized Claude Opus 5 to transform a paragraph from 'Lord of the Rings' into a 3D browser scene, demonstrating the model's potential for on-demand game worlds. The project, which ran for two hours with a budget of one million tokens, highlights the limitations of existing benchmarks like the pelican test, as it produces vibe checks rather than hard metrics.
Andrej Karpathy's use of Claude Opus 5 to create a 3D browser scene from 'Lord of the Rings' illustrates the growing capability of AI to generate immersive game environments on demand. This signals a shift in how developers can leverage AI for rapid prototyping and content creation, potentially reducing development time and costs for game builders and investors in the gaming sector.
This paper presents a training-free paradigm for attributing AI-generated videos, treating it as an instance retrieval task. The proposed method achieves a Rank-1 accuracy of 20.5% and a mean Average Precision of 16.6% on the GenVidBench benchmark, outperforming existing state-of-the-art techniques.
The introduction of a training-free method for attributing AI-generated videos represents a significant advancement in video analysis technology, achieving notable accuracy metrics. This development allows builders and PMs to integrate more efficient attribution systems into their products, while investors may see potential in companies leveraging this technology for content verification and copyright management.